Support Agent
Answers customer questions in Arabic or English from your own documents, always citing where the answer came from — and turns anything it isn't sure about into a ticket for a human.
Built and verified · recorded run, offline test suite, and full source below.
The problem
Small teams answer the same ten questions over and over, and the usual chatbot either invents answers or dead-ends with 'I don't understand'. The useful version does two things a naive bot doesn't: it shows where every answer came from, and it hands off cleanly to a human when it isn't sure.
Pipeline architecture
Documents are chunked, embedded, and stored in Postgres with pgvector. A question retrieves the closest chunks, and the model is only allowed to answer from those, citing the document and section for every claim. Below a confidence threshold the agent skips answering, opens a ticket with a structured summary of the question, and follows up when a human replies.
Recorded run
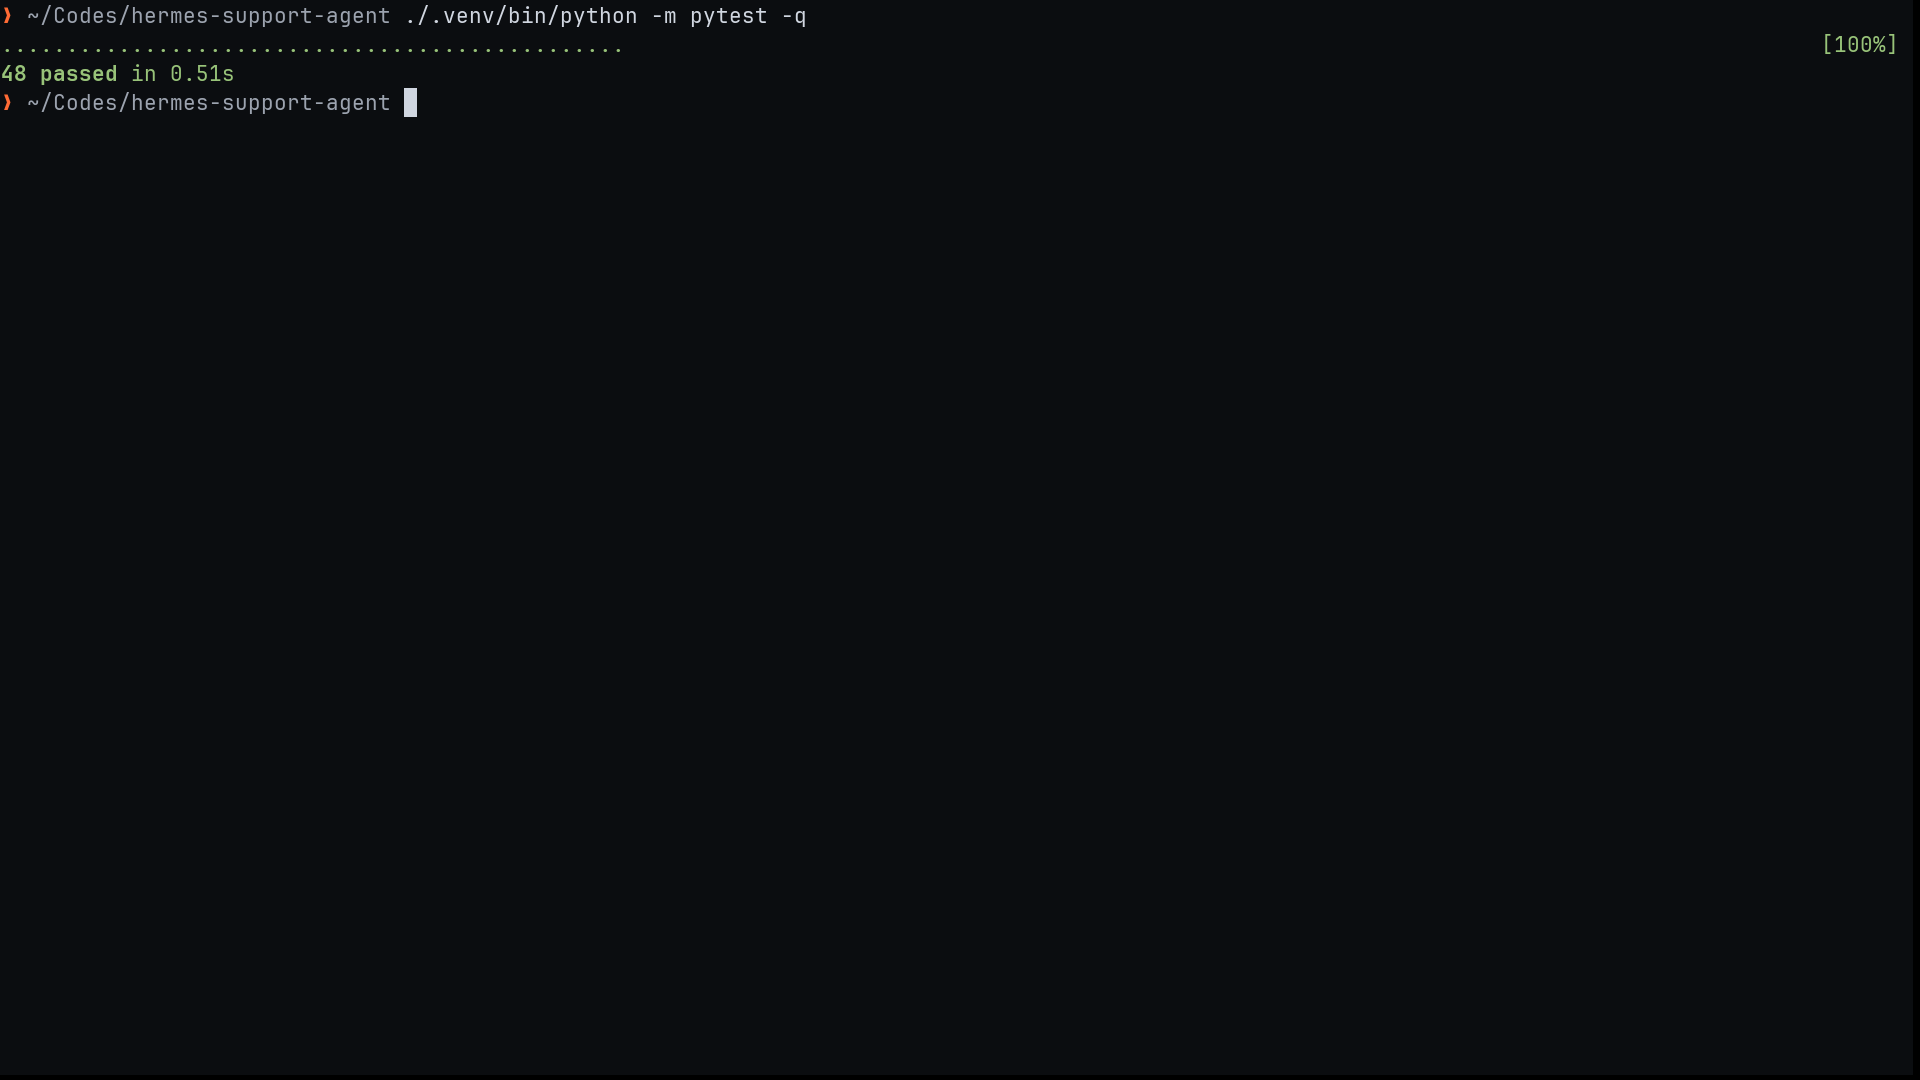
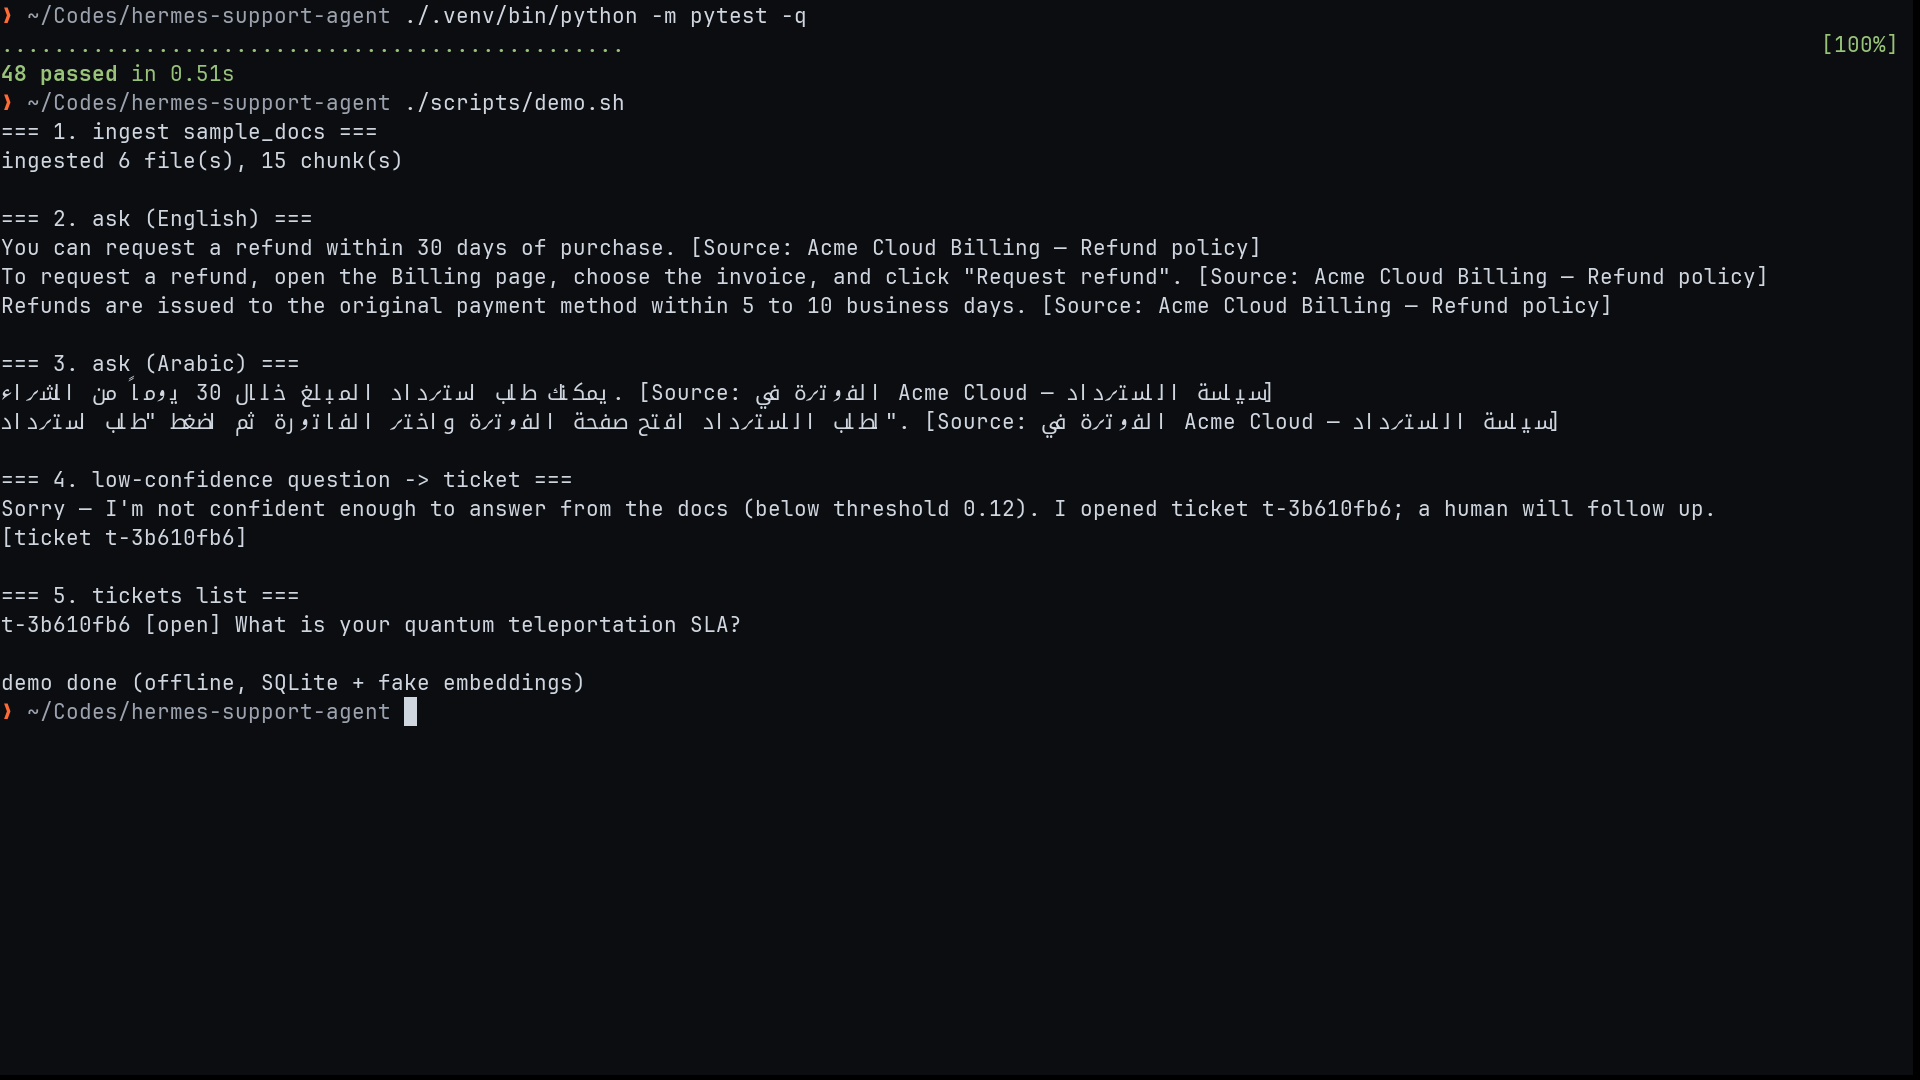
Recorded live in a real terminal: the offline test suite, then ./scripts/demo.sh — the same question answered in English and Arabic with source citations, then a low-confidence question routed to a ticket.
Key decisions
Every answer carries its source
An answer without a document and section behind it is treated as a failure, not sent. That single rule is what makes the bot trustworthy enough to leave running.
Arabic and English from the start
Most of the businesses I'd build this for work in both languages, so the chunking and the evaluation set cover Arabic from day one rather than as a later translation layer.
A ticket instead of a dead end
When confidence is low the agent's job becomes summarizing the question well enough that the human answering it starts ahead, not starting from 'what did they mean?'
Guardrails
- Untrusted document content is treated as data, never as instructions.
- A confidence threshold gates every auto-answer.
- Full conversation logs are kept per ticket for review.
Verification
Targets at least nine of ten answers correctly cited. Verified on the fixed evaluation set: 10/10 correctly cited, every answer carrying a document-and-section citation — both languages visible in the recorded run.